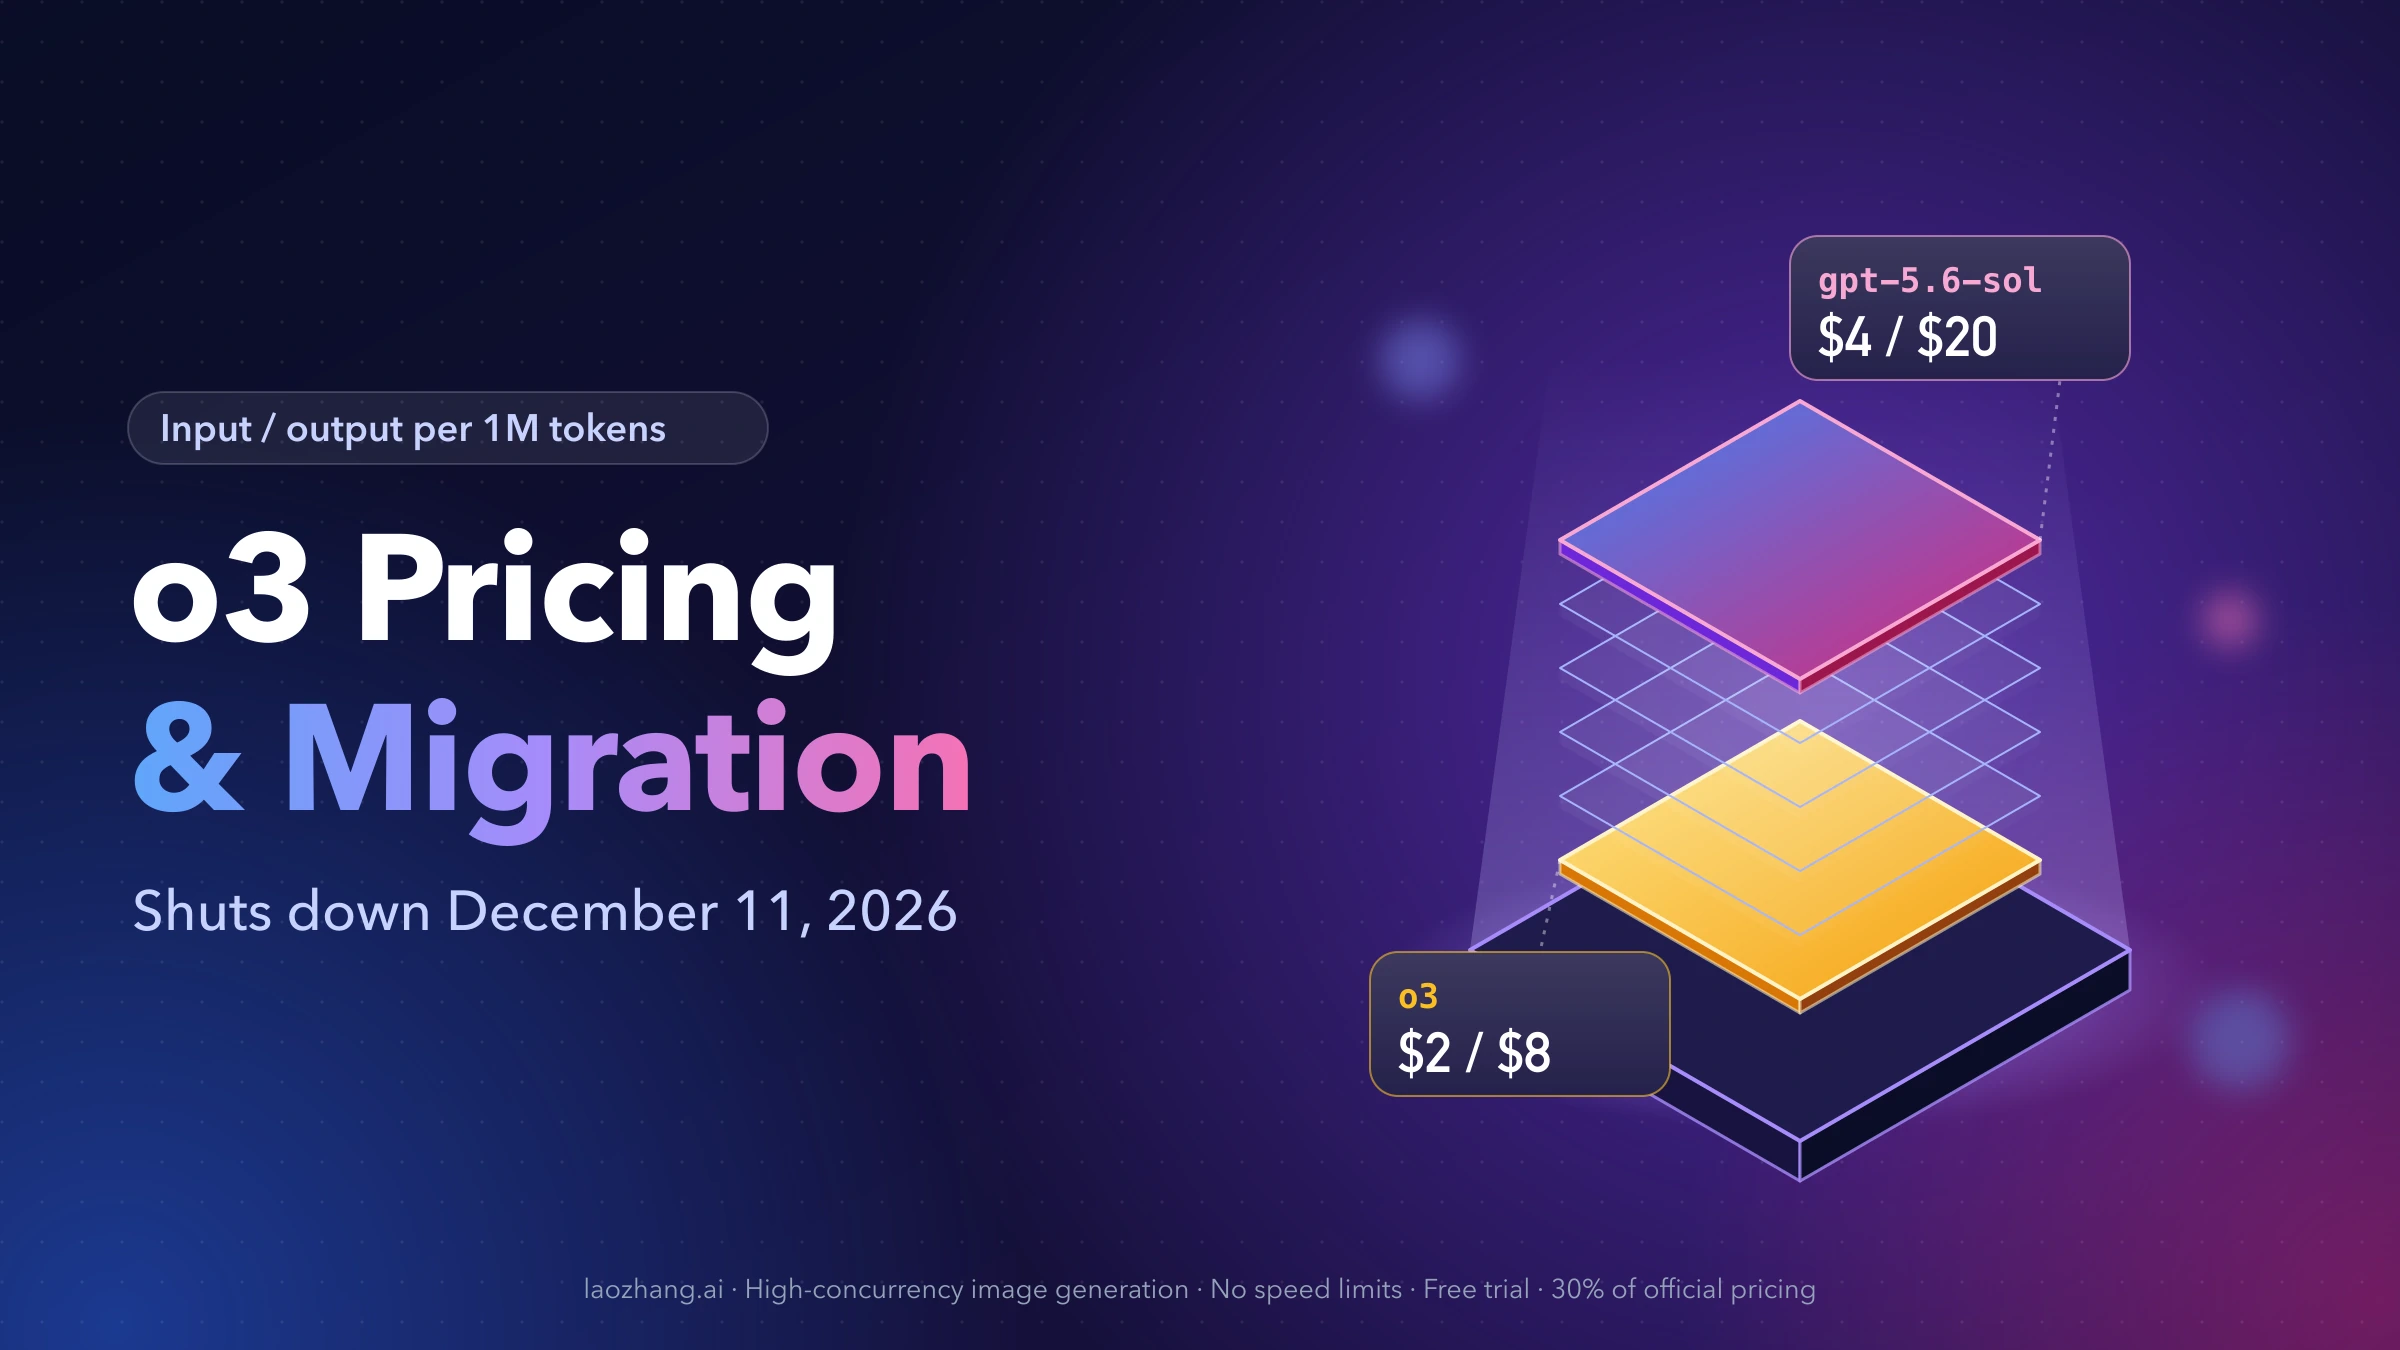
As of September 30, 2026, OpenAI charges $2.00 per 1M input tokens, $0.50 per 1M cached input tokens, and $8.00 per 1M output tokens for o3 on the standard API. The Batch API halves that to $1.00 / $0.25 / $4.00. o3-pro costs $20 per 1M input tokens and $80 per 1M output tokens.
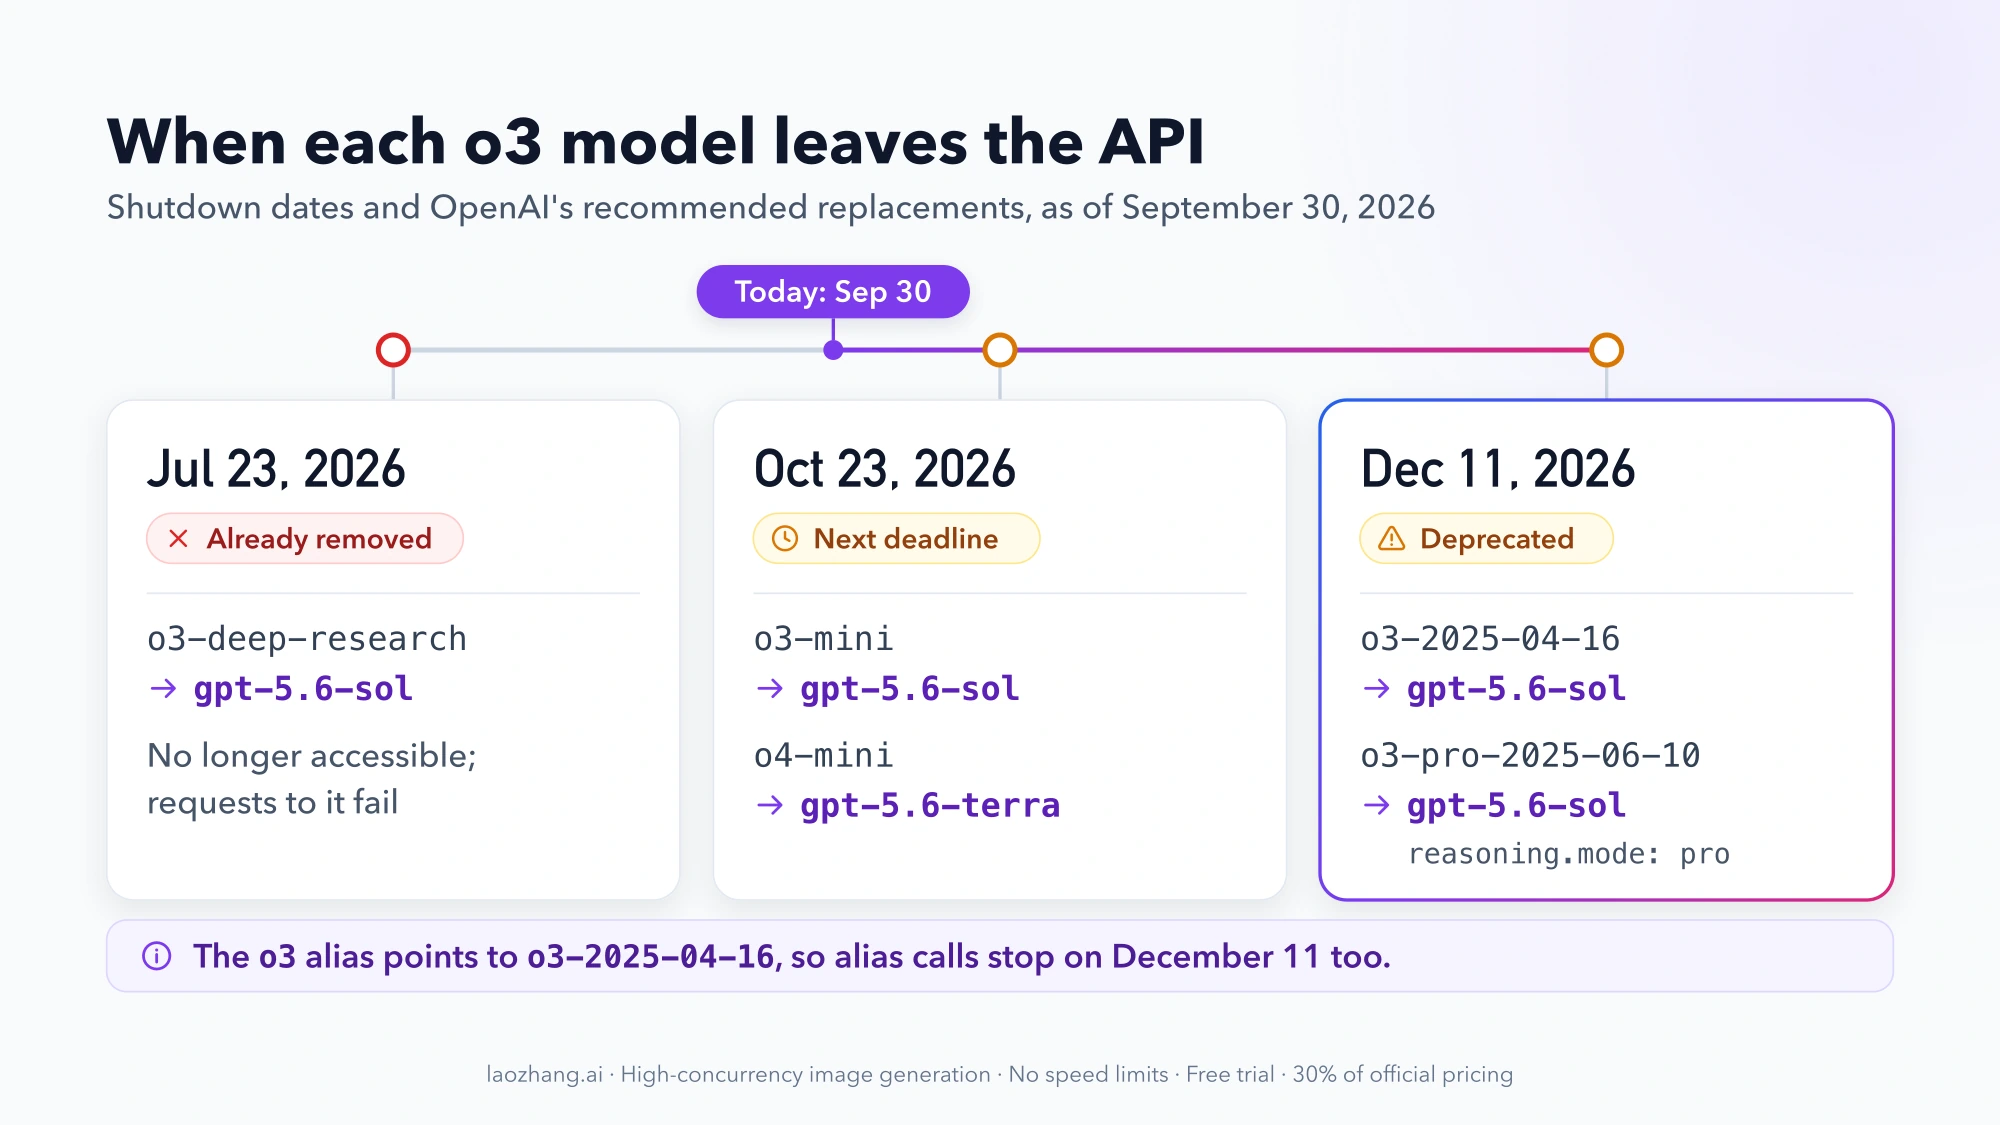
That price has an end date. OpenAI has deprecated the o3-2025-04-16 and o3-pro-2025-06-10 snapshots, and both are removed from the API on December 11, 2026. o3-mini goes earlier, on October 23, 2026. OpenAI's recommended replacement is gpt-5.6-sol, which lists at $4 input and $20 output per 1M tokens, so at the same token counts and without cache hits your bill rises 2–2.5×.
| Model | Input (per 1M) | Cached input (per 1M) | Output (per 1M) | Removed from API |
|---|---|---|---|---|
o3 (o3-2025-04-16) | $2.00 | $0.50 | $8.00 | December 11, 2026 |
o3 via Batch API | $1.00 | $0.25 | $4.00 | December 11, 2026 |
o3-pro (o3-pro-2025-06-10) | $20.00 | — | $80.00 | December 11, 2026 |
o3-mini (o3-mini-2025-01-31) | — | — | — | October 23, 2026 |
Prices come from the o3 and o3-pro model pages; dates come from OpenAI's deprecations page. The o3-mini row only lists its removal date.
What o3 costs on the API today
The o3 model page lists these terms alongside the price:
- Context and output limits: a 200,000-token context window and up to 100,000 output tokens per request.
- Reasoning tokens are billed as output. o3 thinks before it answers, and those hidden reasoning tokens are charged at the $8 output rate even though they never appear in the response text. That is why an o3 bill is often higher than the visible answer suggests. Are Reasoning Tokens Billed? OpenAI, Claude, and Gemini Costs walks through how to read them from the
usageobject. - Endpoints: Chat Completions, Responses, and Batch.
- No free tier. The model page marks the free tier as not supported, so you need a paid API account. OpenAI API Key: How to Get One, Use It, and What It Costs covers prepaid credits and key setup.
- Rate limits: the model page lists Tier 1 at 500 requests per minute and 30,000 tokens per minute, rising to 10,000 RPM and 30,000,000 TPM at Tier 5. Those tier names are the ones printed on the o3 page and may not match the tier names in OpenAI's current rate-limit guide.
o3-pro is a different product at ten times the price. It runs only in the Responses API, and a single request can take several minutes, so OpenAI suggests background mode for it. It shares o3's 200,000-token context and 100,000-token output cap.
ChatGPT subscriptions are billed separately, and the API prices above do not apply to ChatGPT plans.
How much does one o3 request cost? No fixed price per generation
There is no fixed price per generation, because every request uses a different number of tokens. The formula is:
cost = (uncached input tokens × $2.00
      + cached input tokens   × $0.50
      + output tokens         × $8.00) ÷ 1,000,000
Output tokens include reasoning tokens. Here is the math for a hypothetical request with 5,000 input tokens and 4,000 output tokens (visible answer plus reasoning):
| Scenario | Input cost | Output cost | Total |
|---|---|---|---|
| Standard, no cache hits | 5,000 × $2 / 1M = $0.010 | 4,000 × $8 / 1M = $0.032 | $0.042 |
| Standard, 4,000 of the input tokens cached | 1,000 × $2 / 1M + 4,000 × $0.50 / 1M = $0.004 | $0.032 | $0.036 |
| Batch API, no cache hits | 5,000 × $1 / 1M = $0.005 | 4,000 × $4 / 1M = $0.016 | $0.021 |
At those rates, 1,000 input tokens cost $0.002 and 1,000 output tokens cost $0.008. Output costs four times as much as input, so a request that reasons for a long time can cost several times as much as one with the same prompt and a short answer.
Is OpenAI retiring o3?
Yes. On June 11, 2026, OpenAI notified developers that the o3 and o3-pro snapshots are deprecated. "Deprecated" means the models still work today but have a fixed shutdown date. After that date, requests to them fail.
| Model or snapshot | Shutdown date | OpenAI's recommended replacement |
|---|---|---|
o3-2025-04-16 | December 11, 2026 | gpt-5.6-sol |
o3-pro-2025-06-10 | December 11, 2026 | gpt-5.6-sol with reasoning.mode: pro |
o3-mini-2025-01-31 / o3-mini | October 23, 2026 | gpt-5.6-sol |
o4-mini-2025-04-16 / o4-mini | October 23, 2026 | gpt-5.6-terra |
o3-deep-research-2025-06-26 / o3-deep-research | July 23, 2026 (already removed) | gpt-5.6-sol |
Source: OpenAI deprecations page, as of September 30, 2026.
Two details catch people out:
- The
o3alias does not save you. On the model page, theo3alias points too3-2025-04-16, the snapshot marked deprecated. Code that callsmodel="o3"is affected just like code that pins the dated snapshot. - "Succeeded by GPT-5" is outdated guidance. The o3 model page still describes o3 as "succeeded by GPT-5," but the
gpt-5-2025-08-07snapshot is removed on the same December 11 date. Follow the replacement named on the deprecations page instead.
For teams that cannot finish in time, the deprecations page says some developers may be able to provision dedicated capacity for continued access after a shutdown date by contacting OpenAI's sales team. Treat that as an exception to ask about, not a plan.
What moving off o3 does to your bill
The recommended replacement costs more per token. The gpt-5.6-sol model page lists $4.00 input, $0.40 cached input, and $20.00 output per 1M tokens. OpenAI's pricing page notes that GPT-5.6 Sol's promotional pricing is available at least through November 21, 2026. It does not say whether $4/$20 is the promotional rate or the regular one, so recheck it before you finalize a 2027 budget.
gpt-6.1-sol is not OpenAI's named replacement for o3, but its $2.00 input and $10.00 output price sits close to o3's. That makes it worth a test run if cost is your main constraint.
| Per 1M tokens (standard) | o3 | gpt-5.6-sol | gpt-6.1-sol |
|---|---|---|---|
| Input | $2.00 | $4.00 (2.0×) | $2.00 (1.0×) |
| Output | $8.00 | $20.00 (2.5×) | $10.00 (1.25×) |
| Cached input | $0.50 | $0.40 (0.8×) | — |
| Example: 10M input + 2M output per month | $36 | $80 | $40 |
The example row uses the formula from the previous section: o3 is 10 × $2 + 2 × $8 = $36. On gpt-5.6-sol it is 10 × $4 + 2 × $20 = $80, and on gpt-6.1-sol it is 10 × $2 + 2 × $10 = $40. The same workload on the o3 Batch API would be 10 × $1 + 2 × $4 = $18.
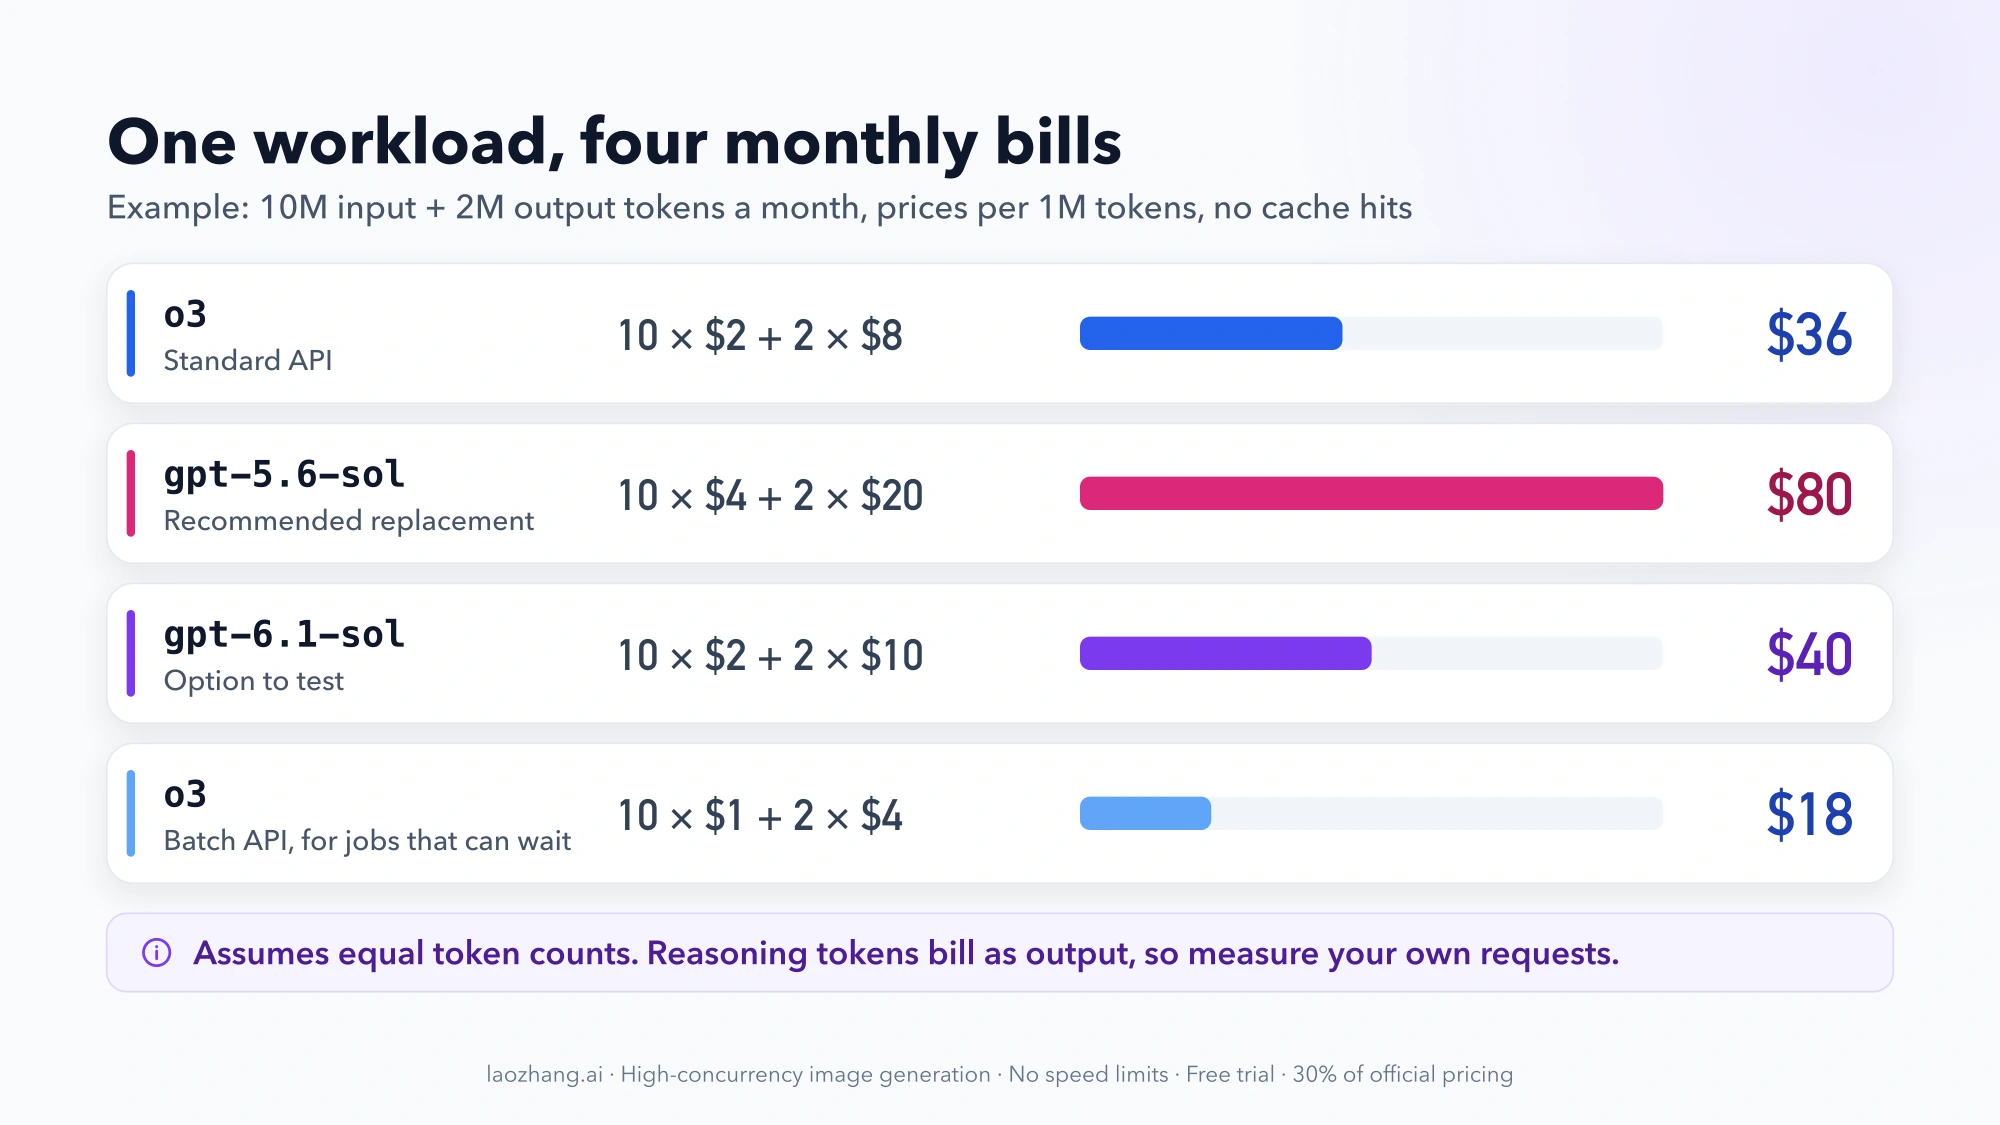
The example holds token counts constant, and that is the weakest assumption in it. Each model reasons differently, and reasoning tokens count as output, so a replacement that uses fewer reasoning tokens can close part of the gap while one that reasons longer widens it. With the same token counts, these rules hold:
- Without cache hits,
gpt-5.6-solcosts 2.0–2.5× what o3 costs. The multiplier leans toward 2.5× as output grows as a share of your tokens. Cached input is the one line where it is cheaper than o3, so prompt-heavy, cache-friendly workloads feel the change least. gpt-6.1-solcosts 1.0–1.25× what o3 costs. It is never cheaper at equal token counts, and the gap is largest for output-heavy jobs.- For
o3-pro, compare against pro mode. The replacement isgpt-5.6-solwithreasoning.mode: pro. Check how the pricing page bills that mode before comparing it with o3-pro's $20/$80.
Both newer models offer a 1,050,000-token context window and up to 128,000 output tokens, compared with o3's 200,000 and 100,000. OpenAI Text Models in 2026: GPT-5.6 Sol, Terra, and Luna Compared helps if you are choosing within the GPT-5.6 family. For GPT-6 cost math, see GPT-6 Luna vs. Sol pricing: calculate the cost of your workload.
Differences to check before switching models
Price is only part of the change. A few API differences can break a straight swap of the model name:
- Reasoning effort settings.
gpt-5.6-solacceptsreasoning.effortvalues fromnonethroughmax, withmediumas the default.gpt-6.1-solacceptslowthroughmaxand does not supportnoneorminimal. Effort changes how many reasoning tokens you pay for, so test the cost at the setting you plan to ship. - Tool calling on
gpt-6.1-sol. Its model page says to use the Responses API for tool calling; Chat Completions works only without tools. If your o3 integration uses function calling through Chat Completions, plan the endpoint move. Chat Completions vs Responses API: Which One Should You Use? covers the trade-offs. - o3-pro jobs already run in the Responses API, often in background mode, so moving them to
gpt-5.6-solin pro mode mostly means changing the model and reasoning settings.
A migration plan that fits before December 11
- Find every call. Search your code and config for
o3,o3-2025-04-16,o3-pro, ando3-mini. Anything ono3-minihas the earlier October 23, 2026 deadline. - Record a baseline. For a representative sample of real requests, log input, cached input, output, and reasoning token counts from the
usageobject, along with the o3 cost. - Replay the same requests on the candidate model. Run them on
gpt-5.6-sol, and ongpt-6.1-solif you want the cheaper option, at the effort level you would ship. Compare output quality on your own tasks and compare the measured token counts, not just the price per token. - Recompute the bill with the formula above and the measured counts. Add the Batch discount back in only for jobs that can wait.
- Switch before the shutdown date and keep the o3 baseline, so you can explain the cost change to whoever owns the budget.
Why some pages still show $10 and $40 for o3
o3 launched in April 2025 at $10 per 1M input tokens, $2.50 cached, and $40 per 1M output tokens. On June 10, 2025, OpenAI cut the o3 price by 80% to $2 input and $8 output, and introduced o3-pro at the same time. Any quote of $10/$40 comes from before that cut. The $2/$8 price has not changed since, and third-party listings such as OpenRouter show the same $2/$8 with $0.50 cached input.
FAQ
How much does o3 cost per 1,000 tokens?
On the standard API, 1,000 input tokens cost $0.002 and 1,000 output tokens cost $0.008. Cached input is $0.0005 per 1,000 tokens. Batch API prices are half of those. Remember that reasoning tokens are billed as output.
Can I keep using o3 after December 11, 2026?
Not through the standard API. After the shutdown date, requests to o3-2025-04-16 and o3-pro-2025-06-10, including requests through the o3 alias, stop working. OpenAI mentions dedicated capacity through its sales team as an option in some cases.
Is o3-pro worth it over o3?
It costs ten times as much per token ($20/$80 versus $2/$8), runs only in the Responses API, and can take minutes per request. Whether that pays off depends on your tasks. Both are removed on the same date, so any new evaluation is better spent on the replacement models.
Is gpt-6.1-sol the official o3 replacement?
No. The deprecations page names gpt-5.6-sol for o3 and gpt-5.6-sol in pro mode for o3-pro. gpt-6.1-sol is a separate model whose price is close to o3's, so it is a reasonable candidate to test, not a drop-in equivalent.