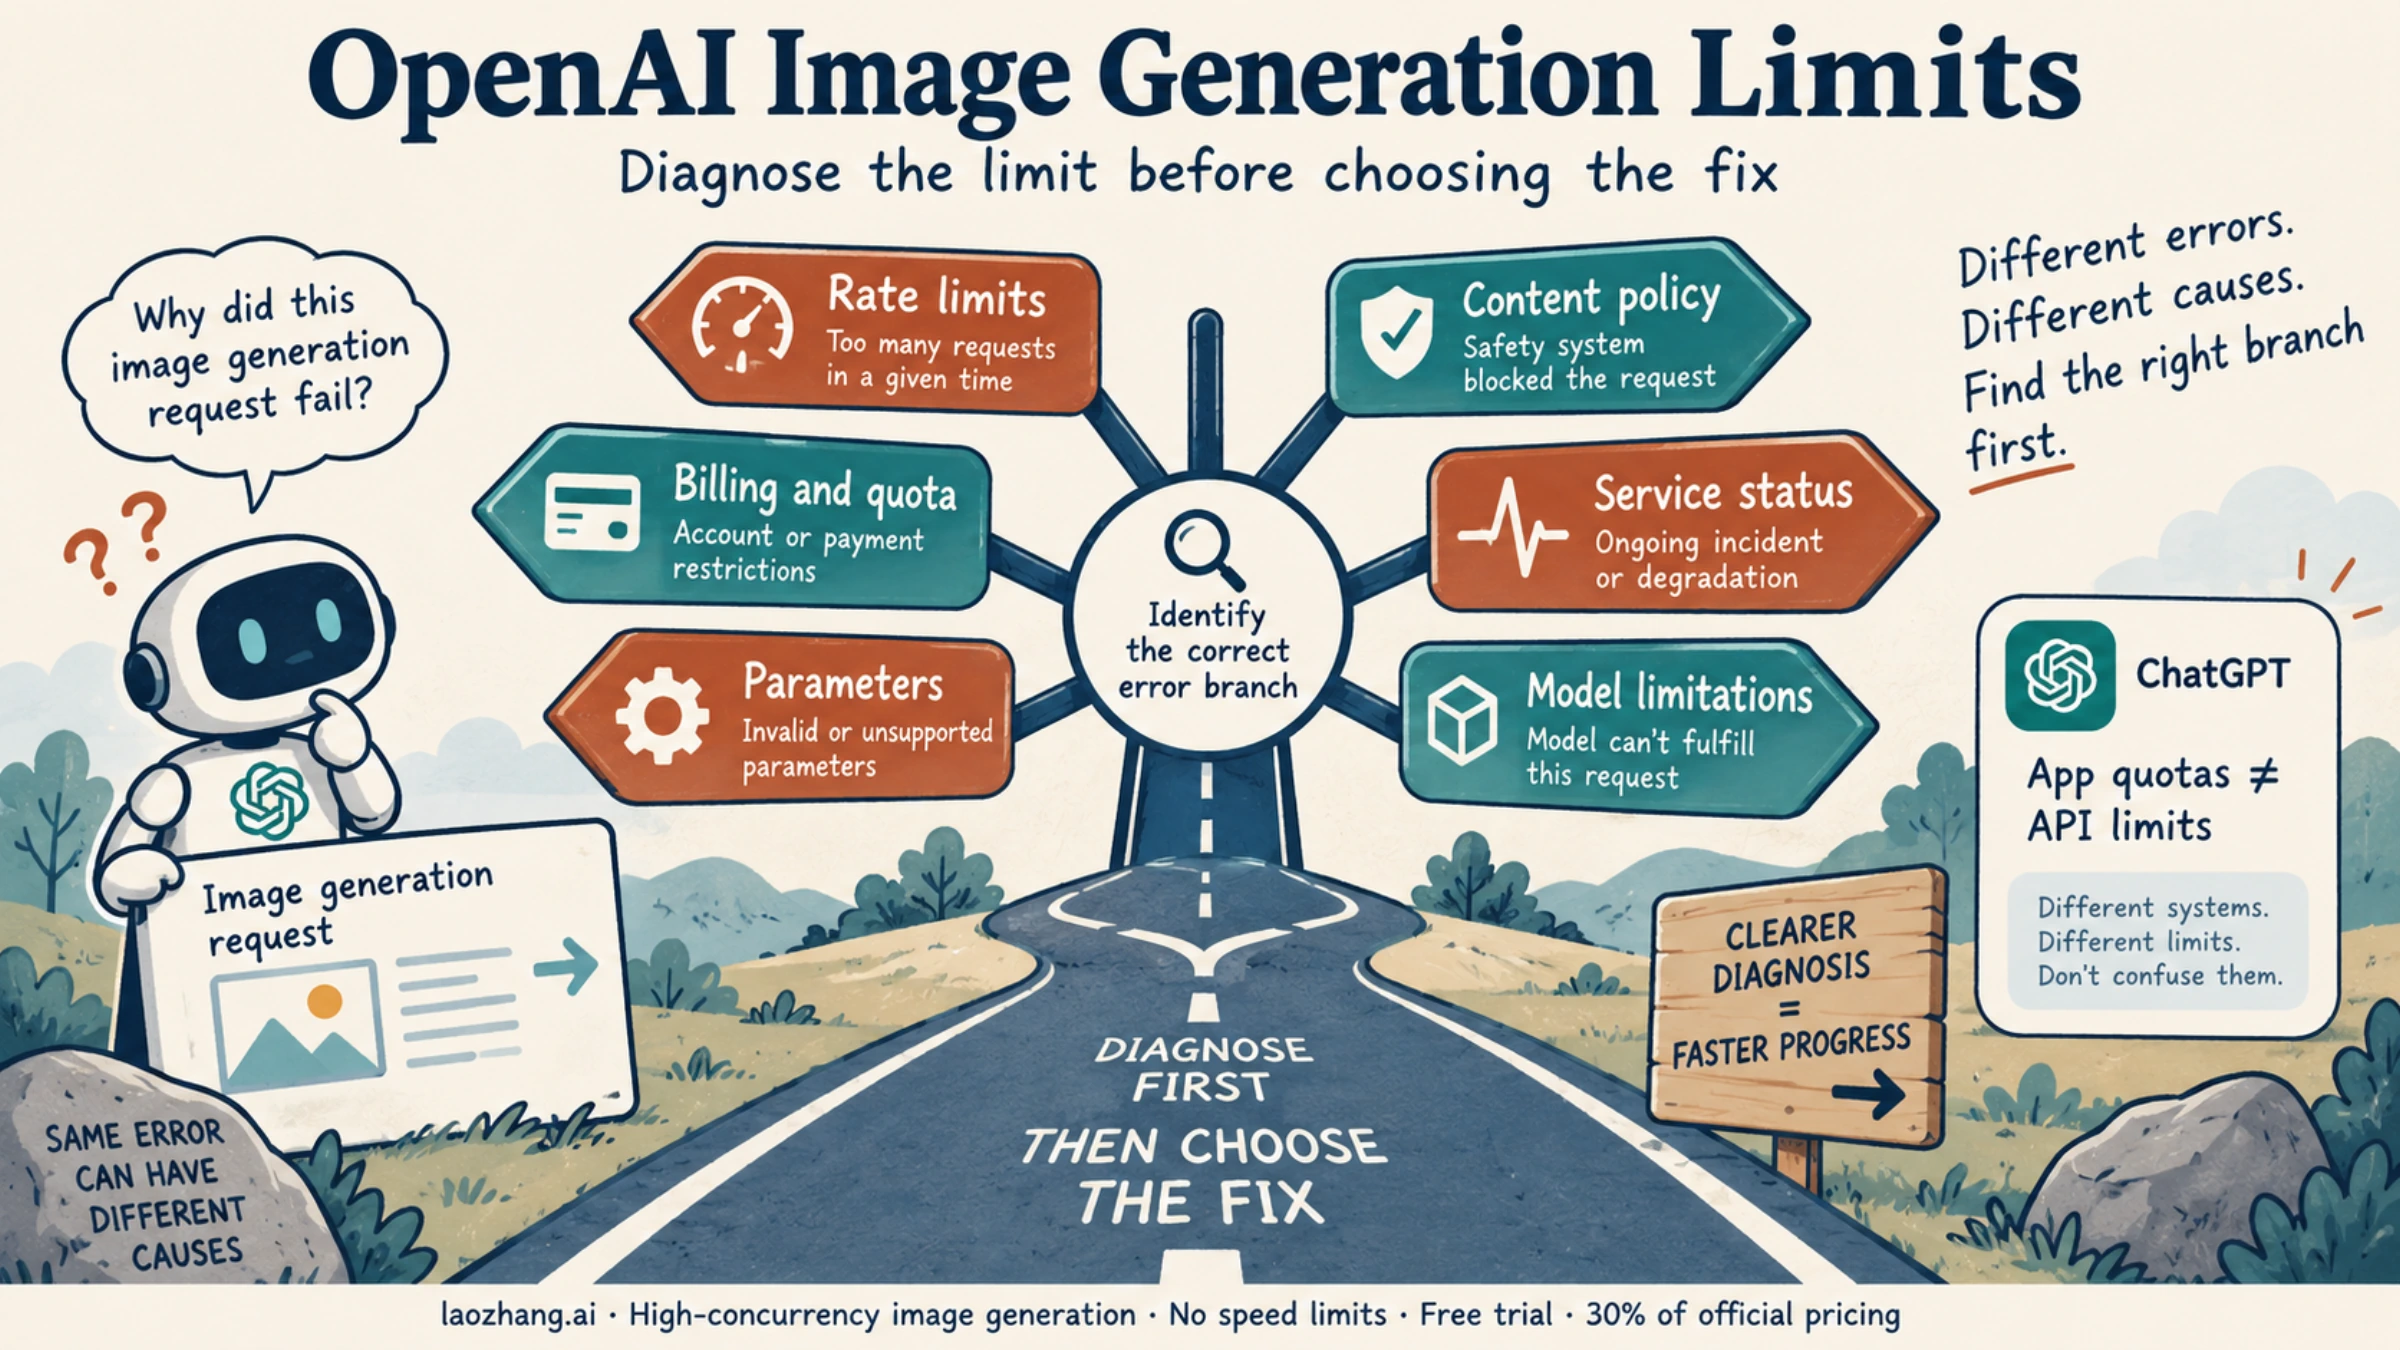
"OpenAI is limiting image generation" covers at least six different things, and they have different fixes. If your API call returned HTTP 429, you hit a rate limit that is set per usage tier: GPT Image models default to 20 images per minute (IPM) and 250,000 tokens per minute (TPM) on the Build tier, 150 IPM / 3,000,000 TPM on Launch, and 250 IPM / 8,000,000 TPM on Grow. If text in your images comes out garbled or a character drifts between generations, you ran into one of the four limitations OpenAI documents for the model itself, and no tier upgrade changes that. If the request was refused with moderation_blocked, it is the content policy. The table below sorts the symptoms; the sections that follow give the documented value or statement for each, with the official page it comes from.
Which OpenAI image generation limit did you hit?
Match what you saw to the row, then jump to that section. Everything here applies to the Images API (/v1/images/generations and /v1/images/edits) unless the row says ChatGPT.
| What you saw | Kind of limit | What changes it |
|---|---|---|
HTTP 429, sometimes with the code slow_down; Retry-After header present | Rate limit: IPM or TPM for your usage tier, counted per organization | Wait out Retry-After, ramp up gradually, or move to a higher tier |
Error code moderation_blocked with moderation_details | Content policy filter on the prompt or the output | Change the prompt or the reference image; the filter applies at every tier |
HTTP 400 about size, n, the mask, or an input image | Parameter and size rules | Fix the parameter; these are hard rules, not quotas |
| Garbled text, inconsistent characters, elements in the wrong place, a request that takes up to 2 minutes | Documented limitations of the model | Prompt and workflow changes; nothing on the account side |
HTTP 503 server_is_overloaded, or slow responses for everyone at once | Capacity, visible on the status page | Back off and retry; check status.openai.com |
| A ChatGPT message that you have reached your image limit | ChatGPT plan quota (not the API) | Covered on separate pages, linked below |
dall-e-3 no longer accepted; account blocked in your country | Availability: model deprecations and supported countries | Switch to a current GPT Image model; use the service from a supported location |
Model limitations: text rendering, consistency, composition control
The image generation guide at developers.openai.com/api/docs/guides/image-generation has a "Limitations" section with four entries plus a note on content moderation. As of October 9, 2026, it says:
- Latency: "Complex prompts may take up to 2 minutes to process." Set client timeouts accordingly; a 60-second client timeout will cut off some legitimate requests.
- Text rendering: "Although significantly improved, the model can still struggle with precise text placement and clarity." If the text must be exact, generate the artwork without it and overlay the text in your own layer.
- Consistency: "While capable of producing consistent imagery, the model may occasionally struggle to maintain visual consistency" for recurring characters or brand elements across generations. Passing reference images through
/v1/images/editsis the documented way to anchor a recurring character or brand element, and the guide positionsgpt-image-2.5-sunburstas the model for workflows "where editing precision matters most". - Composition control: "Despite improved instruction following, the model may have difficulty placing elements precisely" in structured or layout-sensitive compositions. For strict layouts, generate the parts and compose them yourself.
These four statements are what the official documentation says about the model's output quality. They apply to every GPT Image model the guide covers and are independent of your usage tier, your spend, or the endpoint you call.
Content moderation: moderation_blocked and the moderation parameter
The same guide states that "All prompts and generated images are filtered in accordance with our content policy." A blocked request returns the error code moderation_blocked, and the response carries moderation_details with the flagged categories and a moderation_stage of input (your prompt or reference image) or output (the generated image). The input stage means rewording or swapping the reference image is the fix; the output stage means the prompt passed but the result did not, so the prompt needs to steer away from whatever category was flagged.
The request parameter moderation accepts auto (default) and low. Neither value turns the filter off: the guide says it applies to all prompts and generated images. A failed request still counts toward your rate limit, so repeatedly resubmitting a blocked prompt also burns IPM.
OpenAI image generation rate limits by usage tier: 20/150/250 IPM
Rate limits for image models are published as images per minute (IPM) and tokens per minute (TPM), and the default depends on your organization's usage tier. The three current image models carry the same defaults on their model pages (gpt-image-2.5-sunburst, gpt-image-2.5-flare, gpt-image-2):
| Usage tier | How you qualify | Monthly usage cap | Default TPM (image models) | Default IPM |
|---|---|---|---|---|
| Free | Account in an allowed geography | $100 | not shown on the model pages | not shown on the model pages |
| Build | $5 in total credit purchases | $500 | 250,000 | 20 |
| Launch | $100 in total credit purchases | $5,000 | 3,000,000 | 150 |
| Grow | $500 in total credit purchases | $200,000 | 8,000,000 | 250 |
Tier qualification and monthly caps come from the rate limits guide; the TPM and IPM columns come from the model pages. If you remember Tier 1 through Tier 5, that scheme has been replaced by these four names. Tiers upgrade automatically once your total credit purchases cross the threshold, and your actual per-model numbers are under Settings → Organization → Limits, which can differ from the defaults above.
Four details from the rate limits guide decide whether those numbers are enough for you:
- Whichever limit you hit first applies. A job can be well under 20 IPM and still return 429 because the image input tokens on a batch of large reference-image edits exhausted 250,000 TPM.
- Limits are per organization or project, not per user or per API key. Ten developers sharing one organization share one 20 IPM budget. A community report from June 2026 describes a
gpt-image-2limit that appeared to be pooled across accounts in one organization; that matches the documented per-organization scope. - IPM counts images. A request with
n: 4draws four images from the minute's budget, not one. - Failed requests count. Retrying a 429 immediately spends more of the budget you have already exhausted.
Rate limits and QPS for image editing at scale
OpenAI publishes IPM and TPM, not queries per second, and the model pages list one set of defaults per model with no separate figure for /v1/images/edits. Converting the Grow default: 250 IPM ÷ 60 ≈ 4.2 images per second sustained, and 8,000,000 TPM is the token ceiling that reference-image edits will reach first, because gpt-image-2 always processes input images at high fidelity (the input_fidelity parameter cannot be set on that model) and therefore spends more input tokens per edit. For throughput above the Grow defaults, the limits page shows the current values for your account and an Upgrade tier action in the Usage Tiers section; there is no published enterprise rate card for image editing. Non-urgent volume can go through /v1/batch, which the model pages list as a supported endpoint and which prices image output tokens at $15 per million instead of $30.
What "rate limited" means: 429, slow_down, 503, and how to retry
A 429 on an image request means your organization exceeded IPM or TPM for that model in the current minute, or your request rate climbed too fast. The second case returns the error code slow_down, and it can fire even when you are under the RPM and TPM figures on your limits page. Both come with a Retry-After header. The rate limits guide's instructions, as of October 9, 2026:
- Respect
Retry-After. Do not retry before it elapses; failed attempts still count. - Reduce, then ramp gradually. Above roughly 1,000,000 input TPM, raise your rate by no more than 50% every 15 minutes.
- Use exponential backoff with jitter and cap the number of attempts.
- Treat 503
server_is_overloadedseparately. It is capacity, not your quota; wait forRetry-Afteror longer, then retry. - Do not retry quota or billing errors. Those need a credit purchase or a billing fix, and retrying only adds failed requests.
- Read the headers.
Retry-Afterand thex-ratelimit-*headers tell you the remaining budget and the reset timing, so you can throttle before the 429 instead of after.
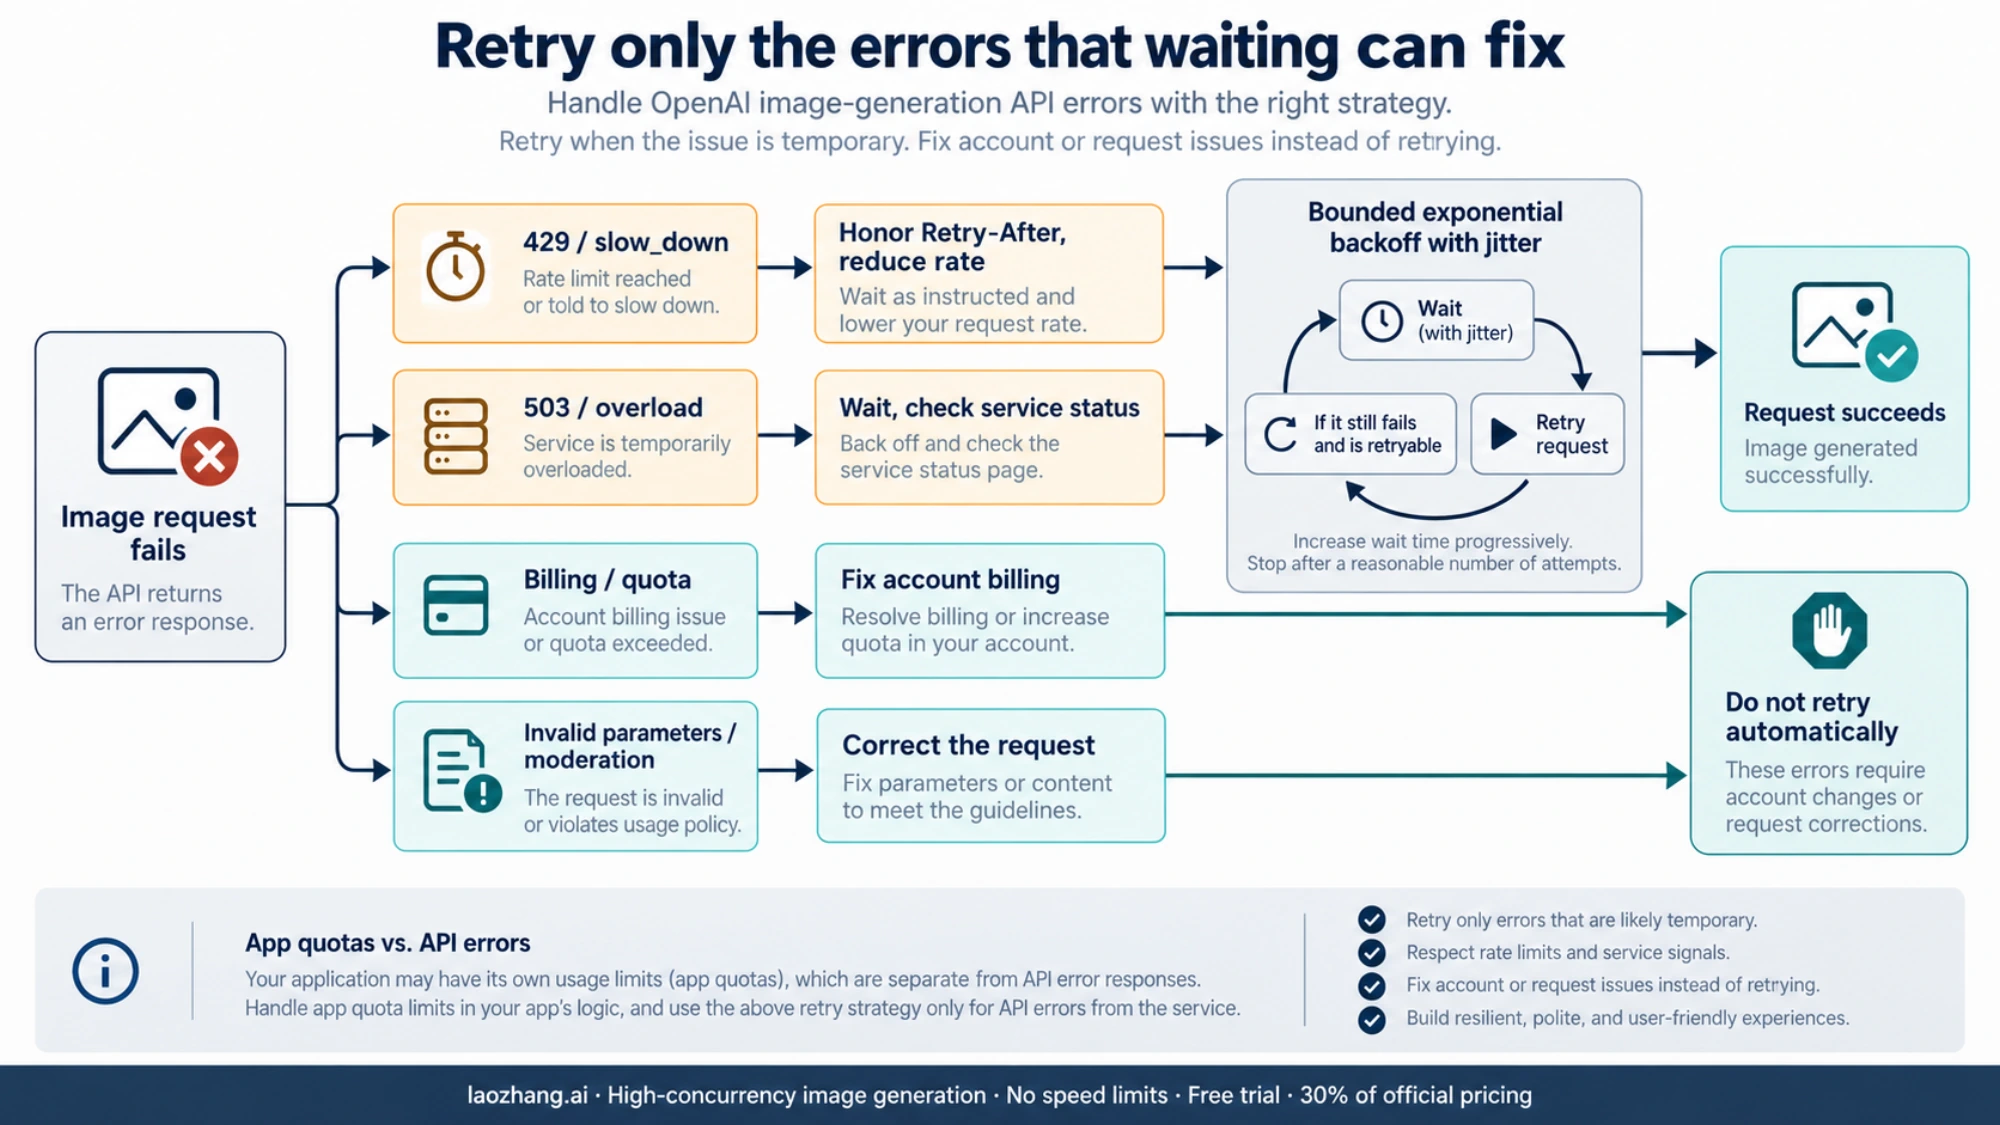
A minimal pattern in Python with the official SDK. It is a fragment: add your own logging and a persistent queue if you run this in production.
import base64
import random
import time

import openai

client = openai.OpenAI()


def generate_with_backoff(prompt: str, max_attempts: int = 5) -> bytes:
    delay = 2.0
    for attempt in range(max_attempts):
        try:
            result = client.images.generate(
                model="gpt-image-2.5-flare",
                prompt=prompt,
                size="1024x1024",
                quality="medium",
                n=1,
            )
            return base64.b64decode(result.data[0].b64_json)
        except openai.RateLimitError as e:  # HTTP 429, including slow_down
            wait = float(e.response.headers.get("retry-after", delay))
        except openai.APIStatusError as e:
            if e.status_code == 503:  # server_is_overloaded
                wait = float(e.response.headers.get("retry-after", delay))
            elif e.status_code in (400, 401, 402, 403):
                raise  # parameter, auth, billing, or moderation: retrying will not help
            else:
                wait = delay
        time.sleep(wait + random.uniform(0, wait / 2))
        delay = min(delay * 2, 60.0)
    raise RuntimeError("image generation still rate limited after retries")
The important choices are in the except branches: 429 and 503 wait for the server's Retry-After when present, backoff doubles with jitter, and 4xx errors other than 429 are raised immediately because they include moderation_blocked, invalid parameters, and billing problems that retries cannot fix.
How to increase OpenAI rate limits for image generation
Three routes, in order of how fast they work:
- Cross the next tier threshold. Buying credits is cumulative: $5 total puts you on Build, $100 on Launch, $500 on Grow, and the upgrade is automatic. The jump from Build to Launch is 20 → 150 IPM, the largest step in the table, so the first $100 of credits buys the biggest increase.
- Request a raise on the limits page. Settings → Organization → Limits shows your per-model numbers and an Upgrade tier action. The defaults above are starting values; the help center's rate limits for image generation article points to the limits page as the place to read your own account's numbers.
- Spend the budget you have more carefully. Keep
nsmall, stay under TPM by shrinking reference images where fidelity does not matter, and smooth bursts with a client-side queue so you never tripslow_down.
Opening a second organization to double the budget is not one of the routes: limits are scoped per organization by design, and the supported countries page warns that accounts used outside the listed locations may be blocked or suspended.
Parameter rules that act like limits: 50 MB masks, 3,840 px, n up to 10
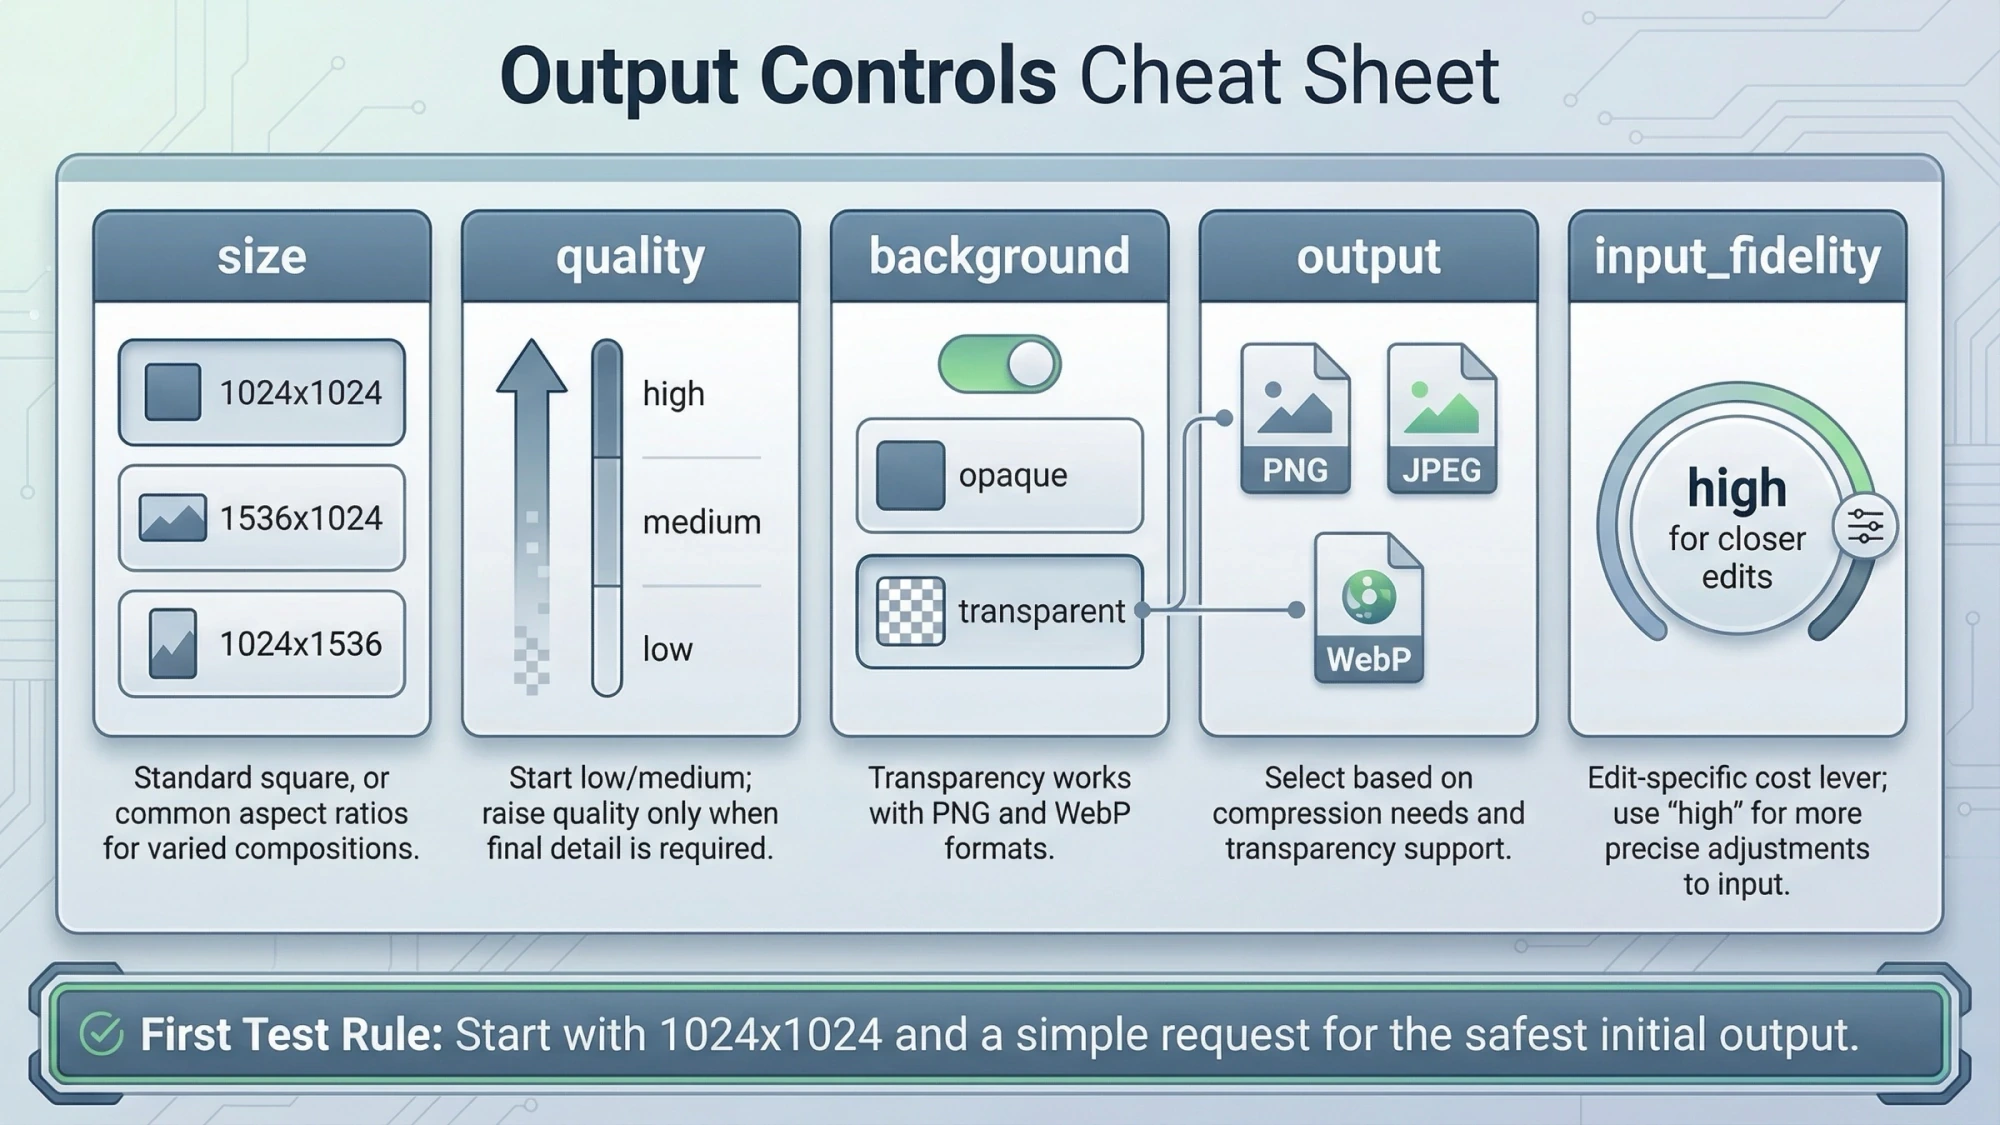
These come from the API reference and the image generation guide. They return HTTP 400 rather than 429, and no tier changes them.
| Rule | Value | Applies to |
|---|---|---|
Images per request (n) | 1–10 | all GPT Image models |
| Prompt length | up to 32,000 characters | all GPT Image models |
size presets | auto, 1024x1024, 1536x1024, 1024x1536; free WIDTHxHEIGHT on the gpt-image-2 family | preset list for all; free sizes for gpt-image-2 family |
| Free-size bounds | longest edge 3,840 px; both edges multiples of 16; aspect ratio no more than 3:1; 655,360 to 8,294,400 total pixels | gpt-image-2 (the guide does not state them separately for 2.5) |
quality | low, medium, high, auto; xhigh and max only on gpt-image-2.5-sunburst and gpt-image-2.5-flare | earlier GPT Image models top out at high |
| Edit inputs | up to 16 input images; the image and its mask must share format and size and be under 50 MB | /v1/images/edits |
input_fidelity | high or low; gpt-image-1-mini only low; omit it for gpt-image-2 | /v1/images/edits |
partial_images | 0–3 with stream; each partial adds 100 output tokens | streaming |
background: "transparent" | needs output_format png or webp; "in preview" on gpt-image-2 | GPT Image models |
| Latency | up to 2 minutes for complex prompts | all GPT Image models |
Two of these interact with rate limits. Every partial image you stream adds output tokens, which count toward TPM. And n multiplies both IPM and output tokens, so a request with n: 10 at quality: "high" is the fastest way to hit a Build-tier limit in a single call.
OpenAI status: "Images" and "Image Generation" degraded performance
status.openai.com lists image generation twice: Images under the API, and Image Generation under ChatGPT. As of October 9, 2026, the page reports "We're fully operational", with uptime of 99.96% for API Images and 99.79% for ChatGPT Image Generation (the lowest figure among the ChatGPT components), and no image incidents in the July–October 2026 history. Those figures move; check the live page when you see trouble.
When either component shows "degraded performance", the practical reading is:
- A 503
server_is_overloadedor a wave of slow responses during a degraded window is capacity, not your limit. Backing off per the retry rules above is the whole fix; raising your tier does nothing. - 429s during a degraded window still mean what they always mean. Your limit did not shrink; the status does not change your IPM.
- For the ChatGPT side (which branch failed, when to stop retrying), the checklist is on ChatGPT Image Generation Not Working? Check Status, Fix the Right Branch, and Stop Wasting Retries.
ChatGPT image limits per plan: where the help center article went
The help center article "Image and video generation limits" (article 8852938), which many people bookmarked for ChatGPT's per-plan image counts, no longer exists; opening it returns the help center's page-not-found message. As of October 9, 2026, OpenAI publishes no fixed per-plan image count for ChatGPT Free, Go, Plus, or Pro. Community threads reported figures such as 40 prompts per 3 hours and 200 images per day in July 2025; those are user reports, not OpenAI statements, and they have changed over time.
If your question is about ChatGPT rather than the API, the plan-by-plan details are on these pages:
- ChatGPT Image Generation Limits per Day 2026: Free, Go, Plus, Pro for the overview across plans.
- ChatGPT Free Plan Image Generation Limits 2026: Per Day, Reset Time for the free plan.
- ChatGPT Go Image Generation Limit per Day: No Official Number for Go.
One thing carries over from the API side: the "text in images" limitation ChatGPT users notice is the same text-rendering limitation documented in the API guide above. It is a property of the model, not of your plan, so upgrading from Plus to Pro does not fix misspelled signage.
DALL·E 3 API availability, deprecations, and 208 supported countries
DALL·E 2 and DALL·E 3 are shut down. The deprecations page records the announcement on November 14, 2025 and the shutdown on May 12, 2026. The model IDs still appear in the API reference's enum, but requests to them no longer work. The help center's rate-limits article still links to DALL·E model pages; treat that as stale.
The rest of the GPT Image line is also moving:
| Model | Status as of October 9, 2026 | Shutdown date | Recommended replacement |
|---|---|---|---|
dall-e-2, dall-e-3 | shut down | May 12, 2026 | gpt-image-2 family |
gpt-image-1 | deprecated (announced April 22, 2026) | October 23, 2026 | gpt-image-2.5-sunburst or gpt-image-2.5-flare |
gpt-image-1.5, gpt-image-1-mini, chatgpt-image-latest | deprecated (announced June 2, 2026) | December 1, 2026 | gpt-image-2.5-sunburst or gpt-image-2.5-flare |
gpt-image-2 | current, not deprecated | — | — |
gpt-image-2.5-sunburst, gpt-image-2.5-flare | current | — | — |
If you came here searching for DALL·E 3 or gpt-image-1 availability: the available models are gpt-image-2.5-sunburst, gpt-image-2.5-flare, and gpt-image-2, and they share the rate limits in the tier table above. Which one to pick is a separate question, answered in OpenAI Image Generation API Models: Which One Should You Use in 2026? and, for the two 2.5 variants, in GPT Image 2.5: Flare vs. Sunburst, Pricing, and API Examples. If the error you see is "Your organization must be verified" rather than a 429, that is an account-state check, not a rate limit; see Fix GPT Image 2's 'Your organization must be verified' Error.
Region availability is not image-specific. OpenAI's supported countries and territories page lists 208 locations where the API and ChatGPT are available (Ukraine with certain exceptions), and warns that "Accessing or offering access to our services outside of the countries and territories listed below ... may result in your account being blocked or suspended." There is no separate list for image models, and the Free usage tier is additionally restricted to an "allowed geography".
Official OpenAI image generation guide and reference pages
Every value above comes from one of these pages. If you only want the primary sources:
| Question | Official page |
|---|---|
| Model limitations, moderation, parameters, size rules, token costs | Image generation guide |
Exact request and response fields for /v1/images/* | Images API reference |
| Usage tiers, 429 and 503 handling, headers | Rate limits guide |
| Default IPM and TPM for each image model | Model pages: gpt-image-2.5-sunburst, gpt-image-2.5-flare, gpt-image-2 |
| Your account's actual limits | Settings → Organization → Limits in the platform dashboard |
| Help center summary | What are the rate limits for Image Generation? |
| Outages and degraded performance | status.openai.com |
| Shutdown dates | Deprecations |
| Where the service is available | Supported countries and territories |
For the choice between the Images API and the Responses tool, see OpenAI Image Generation API Endpoint: Which One to Use, and Why gen_id Isn't One; for what each image costs once you are inside the limits, see GPT Image 2 API Pricing: Cost per Image and Project Budget.
FAQ
What is the rate limit on image generation in ChatGPT?
OpenAI does not publish a fixed per-plan number for ChatGPT as of October 9, 2026, and the help center article that once covered it has been removed. Plan-by-plan details and reset behavior are on ChatGPT Image Generation Limits per Day 2026: Free, Go, Plus, Pro. The API figures above (20/150/250 IPM) do not apply to ChatGPT.
Are OpenAI image rate limits per user, per key, or per organization?
Per organization or project. Every API key in the organization draws from the same IPM and TPM budget for a given model, which is why one teammate's batch job can rate-limit another's single request.
Does the Free tier have an image generation rate limit?
The Free tier exists (an allowed geography, $100 of usage per month), but the GPT Image model pages do not show IPM or TPM values for it. Your limits page shows whether your account can call image models at all and at what rate; the first published defaults are the Build tier's 20 IPM and 250,000 TPM.
Why do I get 429 when I am under my IPM?
Two common reasons. You hit TPM first: large reference images on edits consume image input tokens quickly, and the first limit reached applies. Or your request rate rose too quickly and the response carries slow_down; the fix is to respect Retry-After and ramp up by no more than 50% every 15 minutes once you are above roughly 1,000,000 input TPM.
Does the 2-minute latency count against my rate limit?
No. IPM and TPM count images and tokens per minute, not time spent waiting. Latency matters for a different limit: your own client timeout. Set it above 2 minutes for complex prompts, or the request will fail on your side while still counting toward your IPM.